
October 2026 Maintenance - Sol and Phoenix Upgrades
· 9 min read
Research Computing Team
RC Docs Maintainers

This post summarizes the updates and improvements deployed during the October 2026 maintenance window, a full outage of both Sol and Phoenix from October 12 to October 15. Phoenix returned to service early, on October 13.

Both supercomputers received a Slurm upgrade, a single set of job submission rules shared by Sol and Phoenix, corrected node features, new system images with updated GPU drivers, and software updates.

Slurm Updates

Slurm has been upgraded to 26.05.4 on Sol and Phoenix, including the Sol Gaudi and Grace Hopper nodes, bringing in upstream bug fixes and security updates.

Sol and Phoenix now run the same job submission plugin, so jobs are checked and adjusted the same way on both supercomputers. Changes you may notice:

  • Default memory for GPU jobs. A GPU job that does not request memory now gets the larger of 2 GB per CPU core or a per-GPU minimum: 24 GB per GPU on Sol and 6 GB per GPU on Phoenix. A notice in the job's error output reports the default that was applied. See Memory for GPU jobs.
  • Explicit memory requests are honored. --mem, --mem-per-cpu, and --mem-per-gpu are always honored, with a notice if they are below the minimum. --mem=0 gives the job all of the node's allocatable memory, for CPU and GPU jobs alike.
  • Changing a pending job. On Sol, apart from holding and releasing it, the only change you can make to a pending job is to reduce its time limit. To change cores, memory, GPUs, partition, or QoS, cancel the job and submit it again. See Updating a pending job.
  • Batch scripts are kept. The batch script of every job submitted since October 12 is saved, and you can retrieve the scripts of your own jobs with sacct -j <jobid> --batch-script for about 12 months on Sol and 6 months on Phoenix. See Retrieving a job's batch script.
  • Fairshare. The fairshare calculation was changed to fix an issue that intermittently gave some users the maximum priority regardless of their recent usage. See Fairshare.
  • GPU metrics fixed. A bug that caused GPU usage metrics to be miscalculated or missing for jobs with multiple tasks has been fixed.
  • Old pending jobs removed. Jobs that had been pending since before July 1, 2026 were cancelled. If you still need them, please resubmit.

Idle GPU Jobs Are Cancelled

Starting October 15, running GPU jobs whose GPUs stay completely idle are cancelled, so the GPUs go back to other users. This applies to jobs in the public, private, long, and class QoS on Sol and Phoenix:

  • Idle means 0% GPU utilization. Any GPU use resets the clock.
  • After 2 hours idle, you get an email warning that names the time the job will be cancelled.
  • After 4 hours idle, and never sooner than 2 hours after the warning, the job is cancelled and you get an email saying so.
  • Jobs on your own group's nodes (a grp_ QoS) are not cancelled; their owners get an advisory email instead.

To see how busy your GPUs are, open Slurm › GPU efficiency in the Voyager portal; the warning emails link there.

Node Features and GPU Names

Every node's Slurm features were checked against its actual hardware, and the incorrect ones were fixed on both supercomputers. Features now reflect the hardware that is really in the node: CPU vendor and generation, avx512, the ib or opa interconnect, and GPU model. The phi feature has been removed, since no such nodes exist. If your jobs use --constraint, review the updated node features table.

On Phoenix, the RTX 2080 Ti GPUs that were requested as gtx2080 are now rtx2080, like the other RTX 2080 cards, and the k40 type has been retired. Jobs that still ask for gtx2080 or k40 will be rejected.

System Images and Drivers

All Sol and Phoenix compute nodes were rebooted onto new system images, picking up:

  • Latest kernel and security updates (Rocky Linux 8.10 on x86-64 nodes; Rocky Linux 9.8 on the Sol Gaudi and Grace Hopper nodes)
  • NVIDIA GPU driver updated from 595.71.05 to 615.71.09, supporting CUDA 13.4. Phoenix nodes with V100 and GTX 1080 Ti GPUs, which this driver no longer supports, remain on driver 580.95.05.
  • Intel Gaudi (Habana) driver updated from 1.24.1 to 1.24.2
  • NVIDIA DOCA drivers for ConnectX devices updated from 3.3.0 to 3.5.0
  • On the Grace Hopper nodes, the GPU's HBM memory is managed by the GPU driver rather than appearing as system memory. A job's --mem therefore covers the Grace CPU's memory (up to about 478 GiB), and the GPU's own memory is available to the GPU in full.

Storage

  • Latest updates applied to the Horizon storage system, improving load balancing and performance.

Software and Web Portal

  • Mamba updated to 2.9.0 on Sol and Phoenix
  • Jupyter updated to the latest version on Sol and Phoenix, with Jupyter AI now included
  • Obsolete Mamba environments and Jupyter kernels archived on Sol; contact RC to retrieve them
  • MATLAB Kernel added to Jupyter Notebook on Sol, for using MATLAB in Jupyter Notebook
  • Open OnDemand updated to 4.2 on Sol and Phoenix, with refreshed help menu and messages
  • Posit Assistant added to RStudio on Sol, for using AIR-hosted LLMs in RStudio

AI and the LLM API

The hosted LLM API at https://openai.rc.asu.edu/v1 and the AI tools in the Voyager portal gained these features since the last update. New LLM API guides cover every endpoint, with examples.

  • Streaming text-to-speech. orpheus-3b reads English text aloud in 8 voices, with expression tags such as <laugh> and <sigh>. Audio starts in about 0.3 seconds and streams faster than real time. See Audio.
  • One reasoning-effort scale for every model. reasoning_effort set to none, low, medium or high is translated for each model. Family names such as olmo3-32b and qwen3-235b-a22b choose the instruct or the thinking model by level. See Reasoning effort.
  • Verdicts API. POST /v1/verdicts returns typed answers (yes or no, a choice, or a score) with probabilities, for screening, labeling, and rubric scoring, and can answer questions about images. model is optional and defaults to gemma4-31b-it. See Verdicts API.
  • Models that search the web. Chat models such as glm-5-3 can now search the web on their own during a chat and cite what they find. See Web search.
  • A more detailed model list. GET /v1/models now describes each model: its context window, whether it supports tools, images, and JSON schemas, its reasoning levels, and the abilities the gateway adds to it. See Pick a model.
  • 60-minute request limit. Every model now accepts requests that run for up to 60 minutes, streamed or not. A stream cut off at the limit ends with an error event instead of a normal finish. See Limits and Errors.
  • Ask Voyager. The Ask button in the Voyager portal opens an assistant that answers questions about your jobs, software, storage, and account from your own account data and this documentation. It can also draft software, group membership, and sponsor requests for you to review and submit. It runs on an RC-hosted model, and its answers can be wrong, so check them before relying on them.
  • Jupyter AI in Jupyter. Jupyter on Sol and Phoenix now includes Jupyter AI, a chat assistant in JupyterLab that can use the RC models with your API key. See Jupyter AI.
  • Connect AI agents to your account. The Voyager MCP server lets agents such as Claude Code, OpenCode, and VS Code read your jobs, GPU efficiency, allocations, and storage, limited to the access you choose. See Connect AI Agents to Your RC Account.
  • OpenCode. Sign in to OpenCode with your ASU account, without an API key, from the ASU network or the VPN. The OpenCode tab under AI LLM in Voyager builds a configuration in four steps, and the Skills tab has skills for working on Sol and Phoenix. See Set Up OpenCode.
  • Keys from the older gateway are marked Legacy in Voyager. They keep working, but newer endpoints such as Verdicts need a current key: rotate the key on the AI LLM tab.
  • Model retirements. glm-4-5v retires on October 19 (use gemma4-31b-it), and llama3-groq-70b-tool-use on October 22 (use qwen36-35b-a3b). Until then, responses from them carry Deprecation and Sunset headers.

Benchmarking

The public A100_80 GPUs on Sol were benchmarked with HPL (Linpack) from the NVIDIA HPC-Benchmarks Container v26.02.

DateGPUsRmax (PFLOPS)Per-GPU (TFLOPS)Rpeak (TFLOPS)Efficiency
Oct 20252402.62010.924,68056.0%
May 20262242.61711.684,36859.9%
Oct 20262402.81511.734,68060.1%

MPI point-to-point bandwidth and latency between two Sol CPU nodes were measured with the OSU Micro-Benchmarks 7.5.2, using openmpi/5.0.8-gcc-15.2.0, mpich/4.3.2-srun-gcc-15.2.0, and hpcx/2.25.1.

Both axes are logarithmic.
Point-to-point bandwidth
osu_bw · MB/s · higher is better
Open MPIMPICHHPC-X
Point-to-point latency
osu_latency · µs · lower is better
Open MPIMPICHHPC-X

Technical Updates

  • Slurm updated to 26.05.4 on Sol and Phoenix
  • Job submission rules unified across Sol and Phoenix, with new GPU memory defaults
  • Batch-script archiving enabled in Slurm accounting
  • Fairshare calculation fixed on Sol and Phoenix
  • Node features corrected to match the hardware on both supercomputers
  • NVIDIA GPU driver updated to 615.71.09, supporting CUDA 13.4 (580.95.05 on Phoenix V100 and GTX 1080 Ti nodes)
  • Intel Gaudi driver updated to 1.24.2
  • NVIDIA DOCA drivers updated to 3.5.0
  • Horizon storage updated, improving load balancing and performance
  • GPU metrics fixed for multi-task jobs
  • Idle GPU jobs cancelled after 4 hours at 0% utilization, with a warning email at least 2 hours before
  • Mamba, Jupyter, Jupyter AI, and Open OnDemand updated; MATLAB added to Jupyter Notebook, Posit Assistant added to RStudio
  • Streaming text-to-speech (orpheus-3b) added to the LLM API
  • Reasoning effort, model families, Verdicts, and web search during chats available on the LLM API, with a 60-minute request limit for every model
  • Voyager MCP server and OpenCode sign-in available, and LLM API guides published for every endpoint
  • Ask Voyager assistant turned on in the Voyager portal
  • General kernel and security updates applied to all compute nodes
May 2026 Maintenance - Sol Upgrades

· 3 min read
Research Computing Team
RC Docs Maintainers

This post summarizes the updates and improvements deployed during the May 2026 maintenance window on Sol. Sol received a cluster-wide firmware refresh, an updated kernel and driver stack, a Slurm upgrade with a new job submit plugin, and a refreshed GPU resource naming scheme to improve clarity for users.

GPU Resource Naming

The naming of A100 GPU resources on Sol has been updated to improve readability and make it easier to target a specific class of GPU. MIG (Multi-Instance GPU) functionality, performance, and availability are unchanged; only the resource names that users specify in job scripts have been updated.

New naming convention:

  • 20 GB A100 "MIG" slice → a100.20gb
  • 40 GB A100 GPU → a100.40gb
  • 80 GB A100 GPU → a100 (unchanged for compatibility)

To request a specific GPU type, update your job scripts and interactive commands accordingly:

#SBATCH -G a100.20gb:1
#SBATCH -G a100.40gb:1

Jobs that were pending in the queue specifically targeting the renamed resources will need to be canceled and resubmitted using the new names.

Firmware and Nvidia Driver Updates

Firmware was refreshed across the cluster during this maintenance window. GPU nodes, CPU nodes, and login nodes were all brought current.

As nodes rebooted into the new image, they picked up:

  • Latest kernel and security updates
  • A custom BeeGFS client patch enabling relatime (relative access timestamps), matching the change applied to Phoenix in the March 2026 maintenance. This significantly improves detection of active scratch files, reducing false positives when identifying data for removal.
  • NVIDIA GPU driver updated to 595.71.05 to support CUDA 13.2
  • ROCm and AMD GPU drivers updated to 7.2.3
  • Updated NVIDIA DOCA drivers for ConnectX devices

Slurm Updates

Slurm has been upgraded to 25.11.6 on Sol, bringing in upstream bug fixes and security updates. Alongside the version bump, a new job_submit.lua plugin was deployed with an accompanying test suite that exercises every condo QOS, ensuring job submission rules behave consistently across partitions. Partition sets have also been simplified to reduce confusion when selecting where to run jobs, and outdated class accounts have been removed.

GPU Benchmarking

A selected subset of the public A100_80 GPUs were benchmarked with the Nvidia HPC-Benchmarks Container, specifically the HPL benchmark.

YearGPUsRmax (PFLOPS)Per-GPU (TFLOPS)Rpeak (TFLOPS)Efficiency
20252402.62010.924,68056.0%
20262242.61711.684,36859.9%
Δ−16−0.1%+7.0%—+3.9 pp

The 2026 software/driver stack delivers a measurable efficiency gain over the 2025 baseline.

Technical Updates

  • Slurm updated to 25.11.6 on Sol
  • BeeGFS servers updated from 7.4.6 to 7.4.7
  • BeeGFS relatime patch applied to Sol clients, improving detection of active scratch files
  • NVIDIA GPU driver updated to 595.71.05 (CUDA 13.2 support) across the cluster
  • ROCm and AMD GPU drivers updated to 7.2.3
  • NVIDIA DOCA drivers updated for ConnectX devices
  • Home directories now statically mounted on Sol, improving reliability (/data directories remain dynamically mounted on demand)
  • Open OnDemand updated on Sol
  • Mamba, Jupyter, and Jupyter AI updated to the latest versions
  • Obsolete Mamba environments and Jupyter kernels hidden from the OOD interface
  • General firmware, kernel, and security updates applied to all systems

March 2026 Maintenance - Phoenix Network and Storage Upgrades

· 4 min read
Research Computing Team
RC Docs Maintainers

This post summarizes the updates and improvements deployed during the March 2026 maintenance window. Phoenix received major enhancements to its Ethernet networking and bug fixes to the Scratch filesystem.

Network Upgrades

Phoenix's core Ethernet network has been upgraded from 10/25 Gb/s to 40/100 Gb/s, quadrupling the aggregate bandwidth between racks to up to 200 Gb/s. This provides significantly improved performance for data transfers and network communication.

Scratch Filesystem Improvements

Over the past few months, many users have noticed lag or delays while traversing scratch. This was caused by the client constantly trying to connect over the OmniPath network, even when nodes did not have OmniPath connectivity. This issue has been resolved by forcing the client to maintain connections over the existing network. Users should see improved performance when traversing and accessing scratch.

RDMA connections have also been enabled for scratch, which should further improve performance for users with RDMA-capable network interfaces. This was previously disabled due to a bug in the BeeGFS client disabling RDMA when IPv6 was disabled, which is the case on Phoenix.

We have also applied a custom patch to the BeeGFS client to properly update to relatime (relative access timestamps), which should resolve issues with files appearing to have incorrect timestamps when accessed from Phoenix. Relative access time will update a file's access time on any read or write operation if the previous access time is older than the modification time, or older than 24 hours. Testing has shown that this does not affect the performance of scratch and provides more accurate access times for files on scratch data, which is important for the accuracy of the scratch data retention policy. This patch will be applied to Sol at the next maintenance window.

Scratch Benchmarking

The IO500 benchmarks, a widely used benchmark for evaluating the performance of storage systems in high-performance computing environments, have been run on Phoenix's scratch filesystem to evaluate the performance improvements from the recent updates. The results show that Phoenix's scratch filesystem is capable of delivering high performance for a variety of workloads, including small file access, large file access, and metadata operations. The results even outperform Sol's scratch filesystem in some tests, which is impressive given that Sol's scratch is running on newer hardware.

Benchmark Results:

Test NameSol (March 2023)Phoenix (March 2026)
ior-easy-write12.49 GiB/s22.15 GiB/s
ior-hard-write1.03 GiB/s0.54 GiB/s
ior-easy-read17.15 GiB/s27.31 GiB/s
ior-hard-read1.69 GiB/s2.28 GiB/s
find1433.96 kIOPS1994.09 kIOPS
mdtest-easy-write86.99 kIOPS130.48 kIOPS
mdtest-hard-write8.63 kIOPS7.36 kIOPS
mdtest-easy-stat333.97 kIOPS961.19 kIOPS
mdtest-hard-stat86.93 kIOPS236.19 kIOPS
mdtest-easy-delete58.25 kIOPS129.70 kIOPS
mdtest-hard-delete10.21 kIOPS10.37 kIOPS
mdtest-hard-read11.38 kIOPS20.12 kIOPS
Overall Bandwidth4.40 GiB/s5.23 GiB/s
Overall IOPS61.76 kIOPS102.06 kIOPS
Overall Score16.4823.09

Nvidia GPU Updates

The NVIDIA GPU driver has been updated to 595.45.04 supporting CUDA 13.2. However, NVIDIA has removed support for the Tesla V100 and GTX 1080 Ti GPUs in their latest driver releases. As a result, the V100/GTX 1080 Ti GPUs on Phoenix are currently running on an older driver version (580.95.05) that supports CUDA 13.0.

Technical Updates

  • Slurm updated to 25.11.3
  • Web portals updated to 4.0.10 on Phoenix.
  • Mamba package manager updated to 2.5.0 on Phoenix.
  • Jupyter updated on Phoenix.
  • Obsolete VASP modules removed to clean up module list
  • General security updates applied to all systems
  • InfiniBand cards installed in pcg085-pcg088
  • Home directories are now statically mounted on Phoenix, improving reliability (/data directories are still dynamically mounted on demand)

January 2026 Maintenance - Introducing Phoenix Scratch

· 3 min read
Research Computing Team
RC Docs Maintainers

This post summarizes the updates and improvements deployed during the January 2026 maintenance window. Changes to Sol were minimal, while Phoenix received a major enhancement with the introduction of Phoenix Scratch, a new high performance scratch storage system. Together, these updates improve performance, security, and overall usability across the clusters.

Introducing Phoenix Scratch

Phoenix Scratch Photo

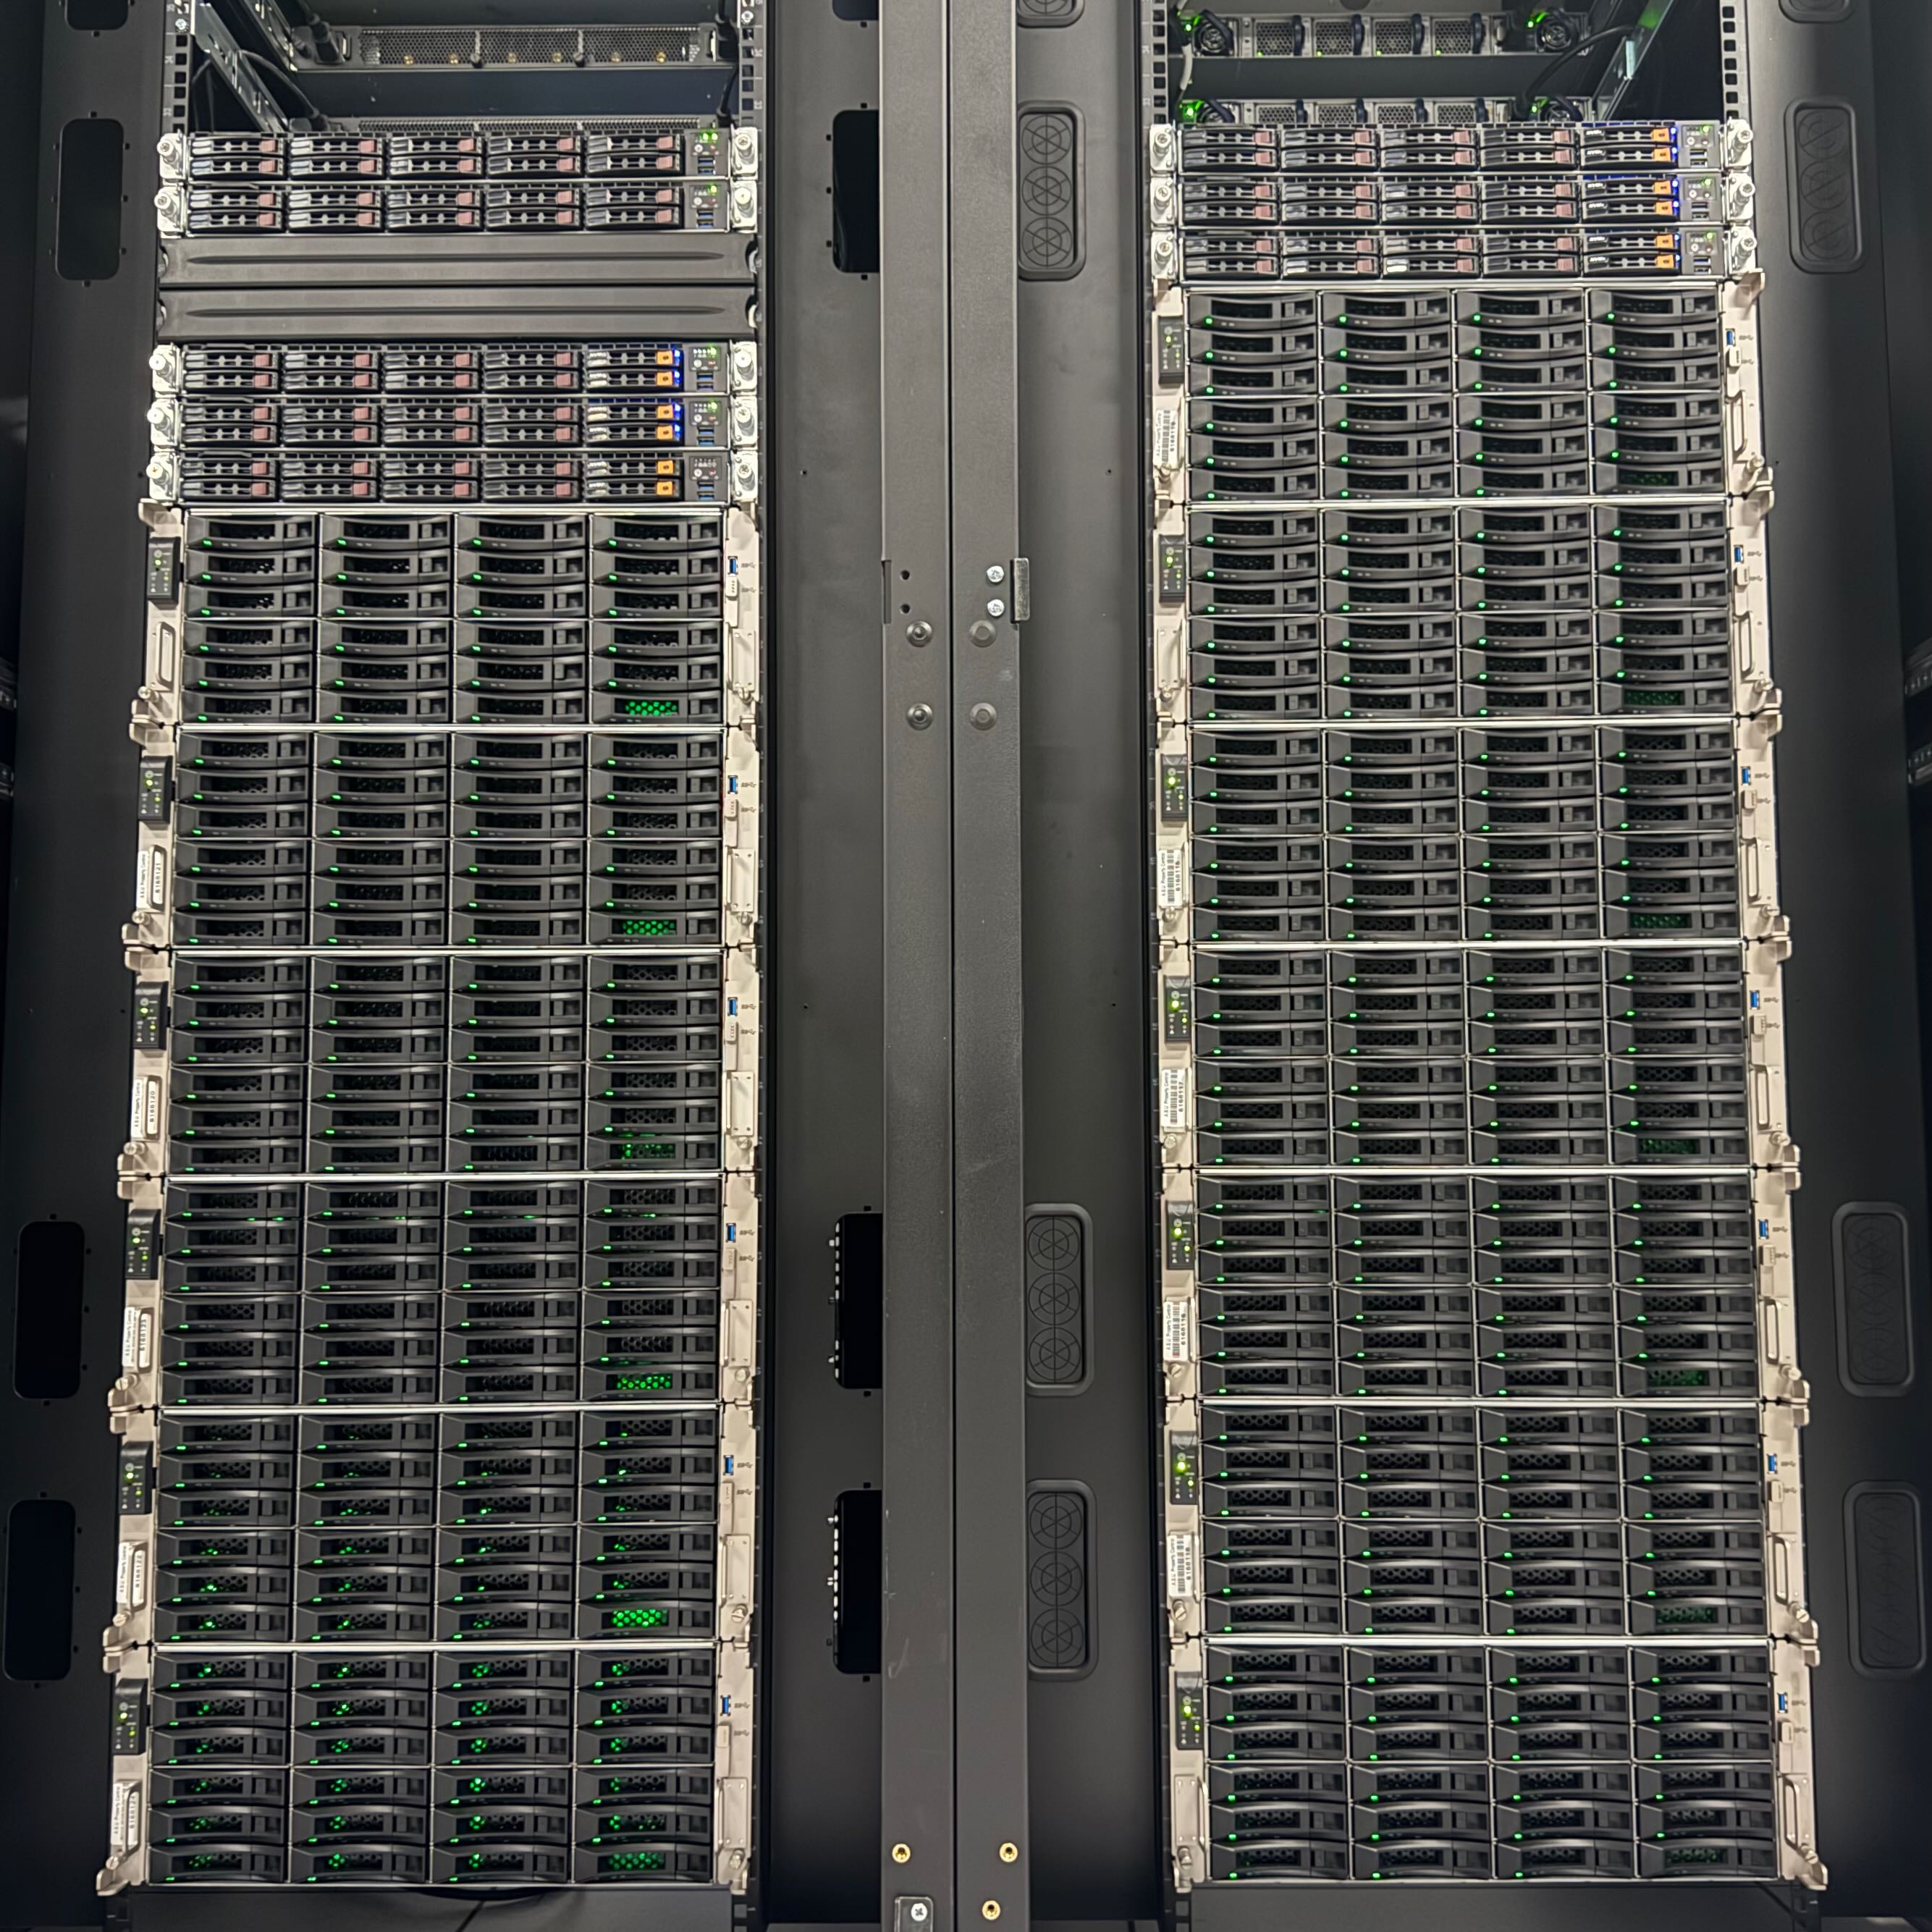
Two racks housing the storage and networking infrastructure for Phoenix Scratch in the Iron Mountain Data Center.

We are pleased to announce the availability of Phoenix Scratch, a new high performance parallel scratch filesystem designed to support data intensive workloads on Phoenix.

  • 3 PiB of shared storage space
  • Directly mountable on InfiniBand, Omni-Path, and Ethernet fabrics
  • High throughput and low latency for I/O intensive applications
  • Parallel file system support for seamless integration with existing workflows
  • NVMe backed metadata for improved responsiveness
  • Policy based quotas for flexible and fair storage management

As with Sol Scratch, Phoenix Scratch is intended for temporary storage only. It is well suited for active job data, checkpoints, and intermediate results, but it should not be used for long term data retention. The automatic 90 day data retention policy applies to both Phoenix and Sols. Users should ensure that important data is backed up to appropriate long term storage systems.

Behind the Build​

Bringing Phoenix Scratch online required significant infrastructure work, including over 800 meters of cabling and the installation of 507 HDDs, 60 SSDs, and 12 NVMe drives across 19 servers. The system is composed of three primary components:

Metadata Servers (MDS): Six high performance servers dedicated to metadata operations, each equipped with NVMe drives. These systems were built using nodes donated by Cirrus Logic and customized to support NVMe storage with drives donated by Intel.

Object Storage Servers (OSS): Thirteen storage servers providing the bulk data capacity and throughput. These systems use a mix of HDDs and SSDs and repurpose hardware previously deployed as the Cholla Storage System.

Networking: Each storage node is connected via 100 Gb Omni-Path, 100 Gb InfiniBand, and dual 40 Gb Ethernet links, ensuring high bandwidth and low latency access regardless of interconnect.

We extend our sincere thanks to our partners at Intel and Cirrus Logic for their generous hardware contributions, which made Phoenix Scratch possible. We also thank our researchers for their patience while Phoenix continued to operate during the deployment and integration of this new filesystem.

Transferring Data to Phoenix Scratch​

Globus is the recommended method for transferring data to and from Phoenix Scratch. We have created a Globus collection specifically for Phoenix Scratch. For more information, see our documentation on transferring data between supercomputers.

Technical Updates

Infrastructure and Firmware​

  • Duo 2FA Enabled for password-based SSH. More information can be found in the Duo 2FA Documentation.
  • Slurm upgraded to 25.11.1 on Sol and Phoenix.
  • Web portals updated to 4.0.8 on Sol and Phoenix.
  • Swap enabled on Sol and Phx login nodes to improve stability during high memory usage.
  • InfiniBand fabrics separated for Sol and Phoenix to improve performance and stability.
  • OmniPath fabric managers updated to 12.0.1
  • Updated Horizon project storage with latest patch release
  • Upgraded Hypervisors to latest stable release.
  • Load-balancing infrastructure updated to improve both security and reliability..